10-K agent
Answers questions from SEC filings
Summary
It answers financial questions about 10-K reports, cites the exact source and checks every figure against XBRL, with search that mixes vectors and BM25. Accuracy went from 35% to 65% over the baseline, and it got 8 of 10 blind questions right. Team of 3.
LangGraph, FAISS and BM25.
The problem
Answer financial questions about the 10-K filings of NVIDIA, Microsoft, Apple, Alphabet, Meta and Amazon for fiscal 2024 and 2025, citing the exact source. A model on its own invents figures or quotes the wrong year. The starting agent, with dense retrieval only, got 35% right on our question set.
How it's built
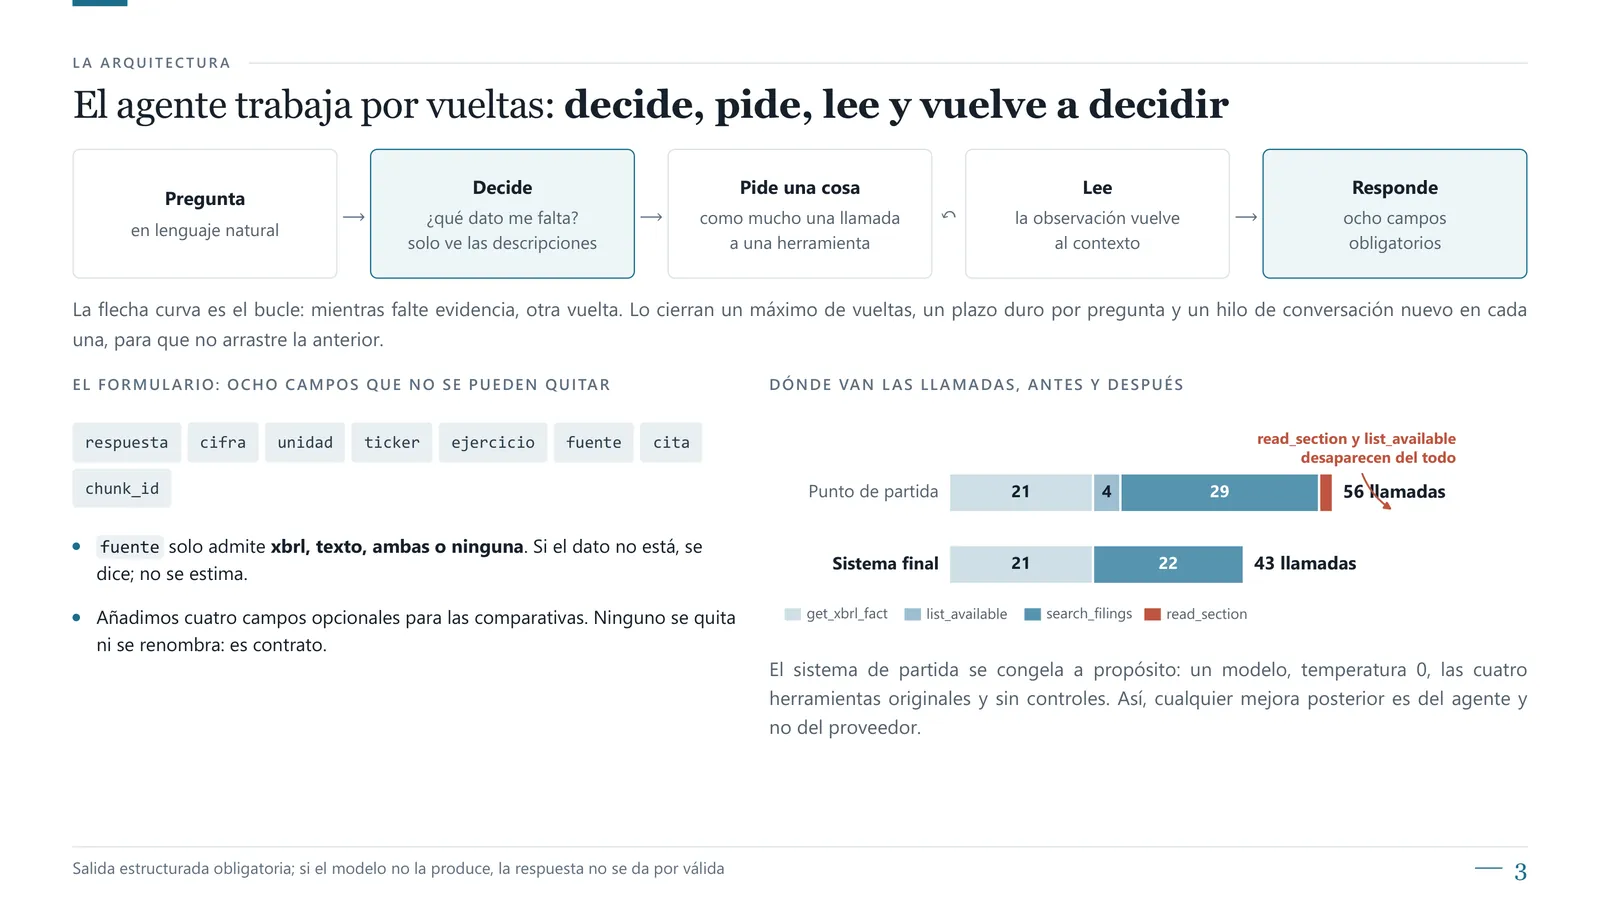
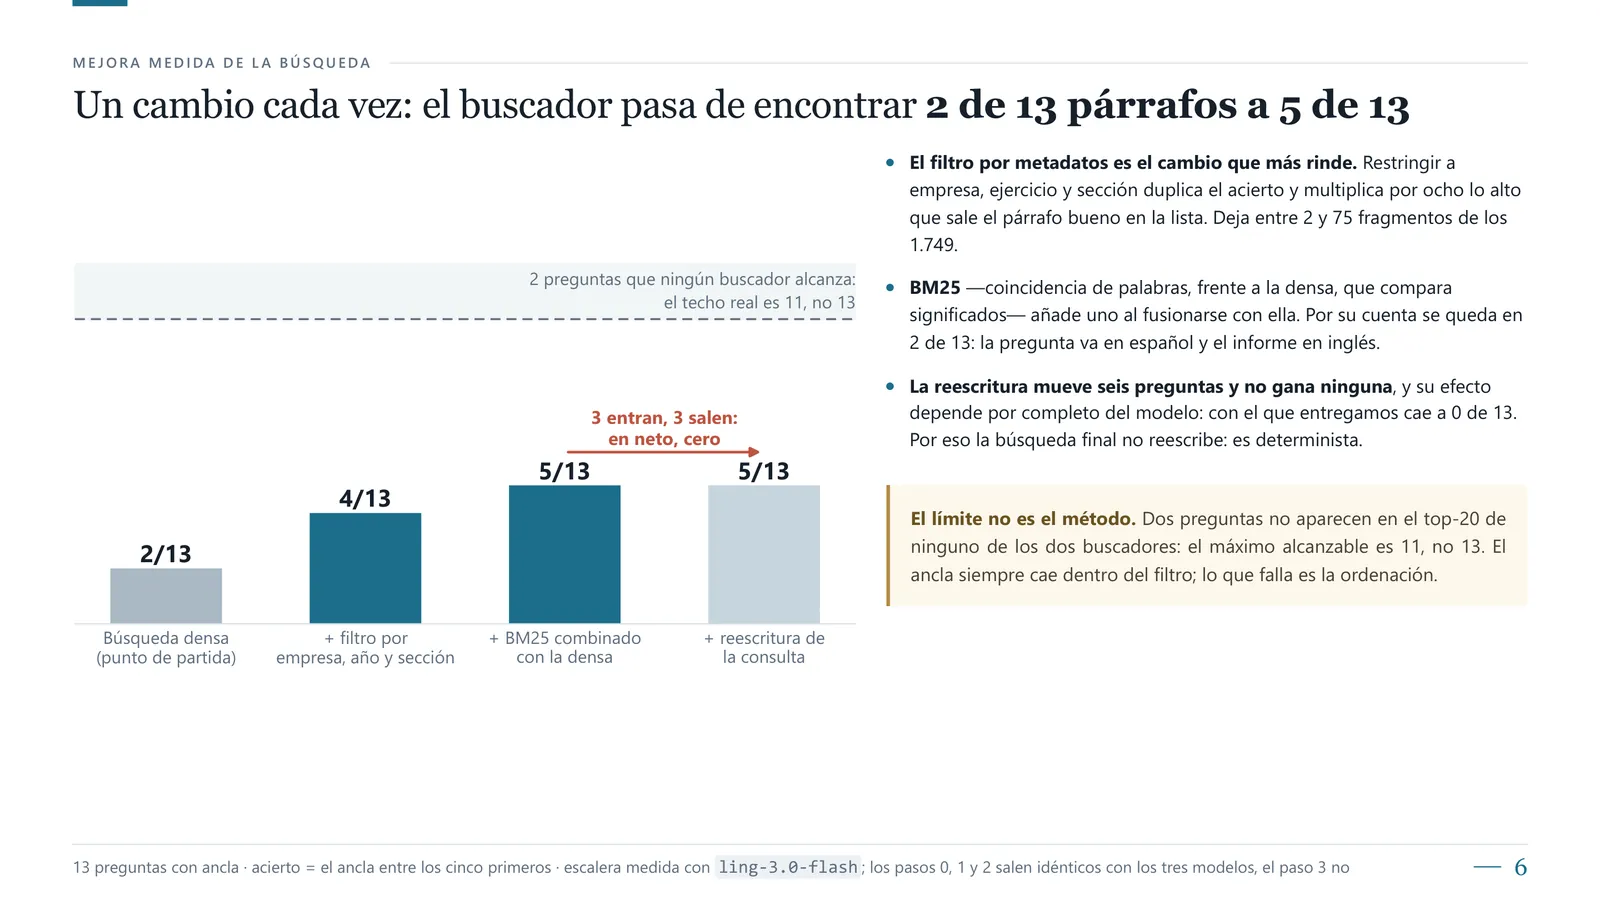
Four tools over XBRL facts and the filing text, with a retrieval ladder measured step by step: filters by company and year, BM25 mixed with vectors through reciprocal rank fusion, and query rewriting. On top sit the guardrails: a limit on calls, a deterministic check of every figure against XBRL, a citation for every numbered sentence, a source derived from what the agent actually retrieved, and a repair step when the structured answer is missing.
We wrote our own golden set: 20 numeric, extractive and comparative questions, plus 6 where the right answer is that the data isn't in the filings.
Results
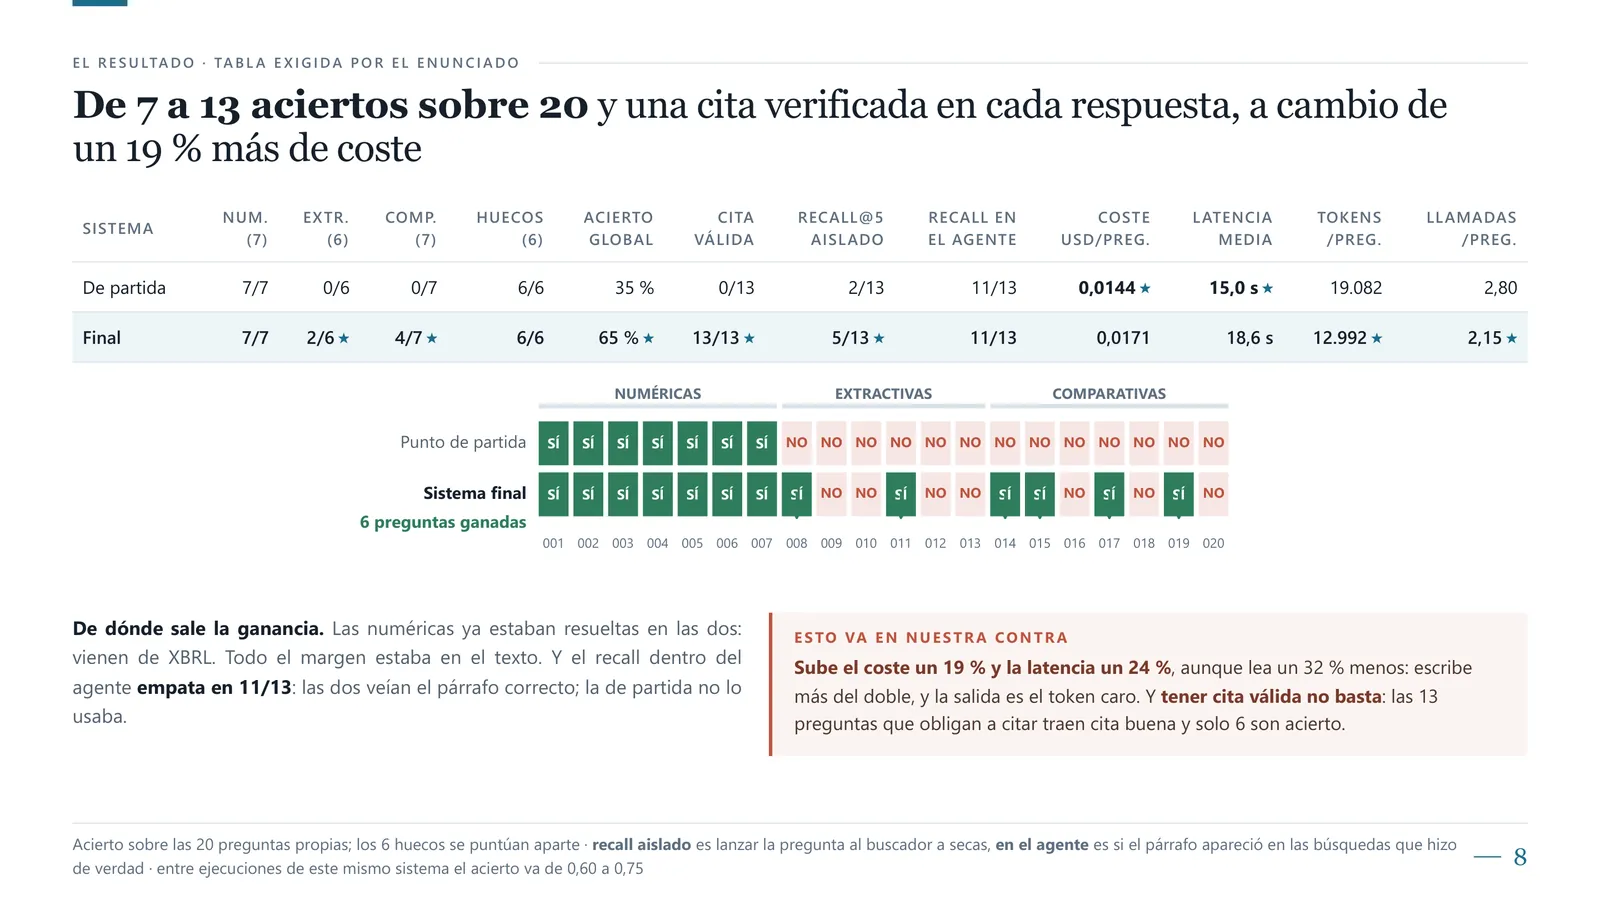
With the same model in both runs, accuracy went from 35% to 65%. Comparative questions went from 0 of 7 to 4 of 7, with fewer calls per question (3.3 to 2.2) at practically the same cost. On the ten blind questions handed out by the course, it got 8 right, in about 15 seconds each.
What I learned
Temperature 0 is not deterministic with every provider. A replica of one run dropped from 75% to 60% with the same code and model; without it we would have reported a 75% that doesn't hold. We also caught our own mistake: one comparison mixed two commits, so it changed three variables instead of one. Checking the commit of every run is now part of the protocol.
Figures