Projects / Master's coursework
Synthetic data
Seven generators for scarce crisis data
Summary
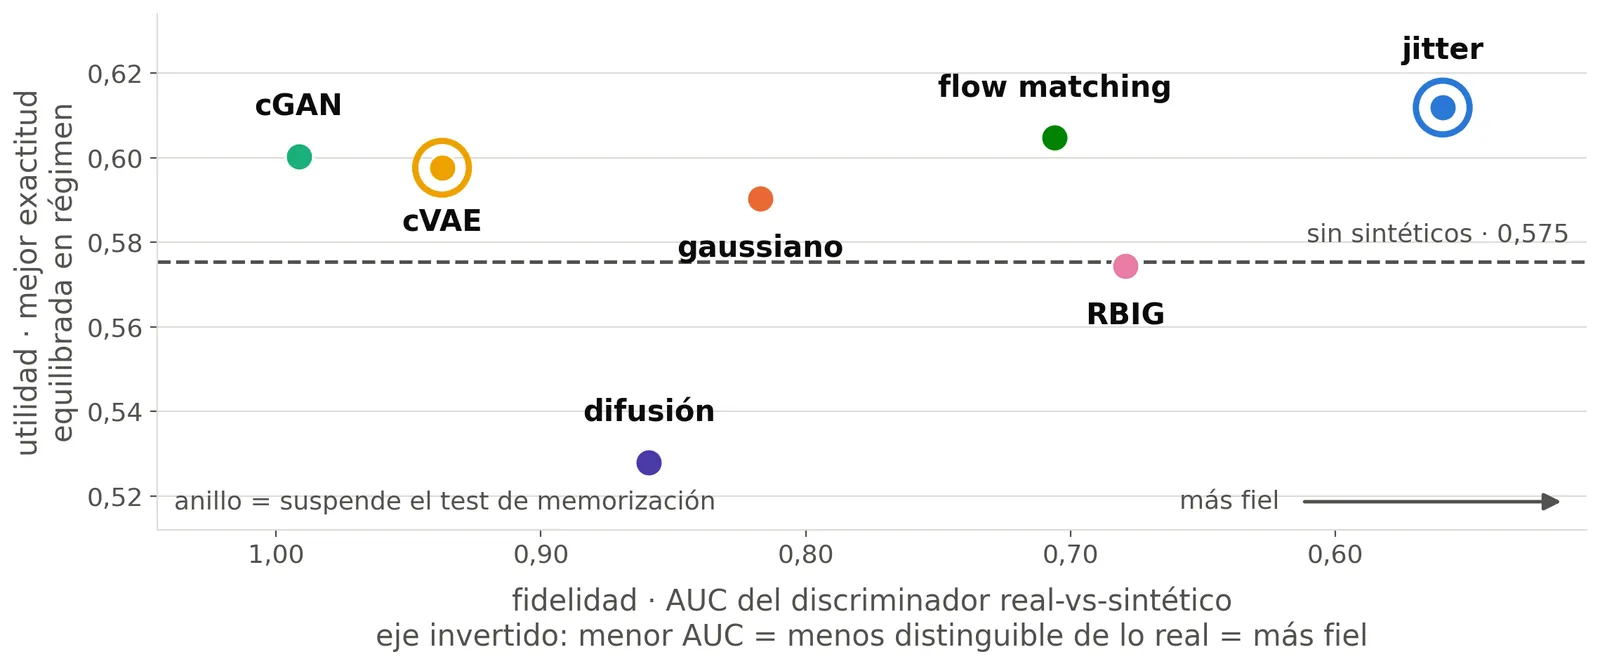
Can synthetic data help when real crises are rare? Seven generators, from added noise to diffusion, and 570 training runs. Synthetic data lifts balanced accuracy from 0.575 to 0.612, but the gain sits inside the noise band, and the most faithful generator came seventh in usefulness. Team of 3.
The question
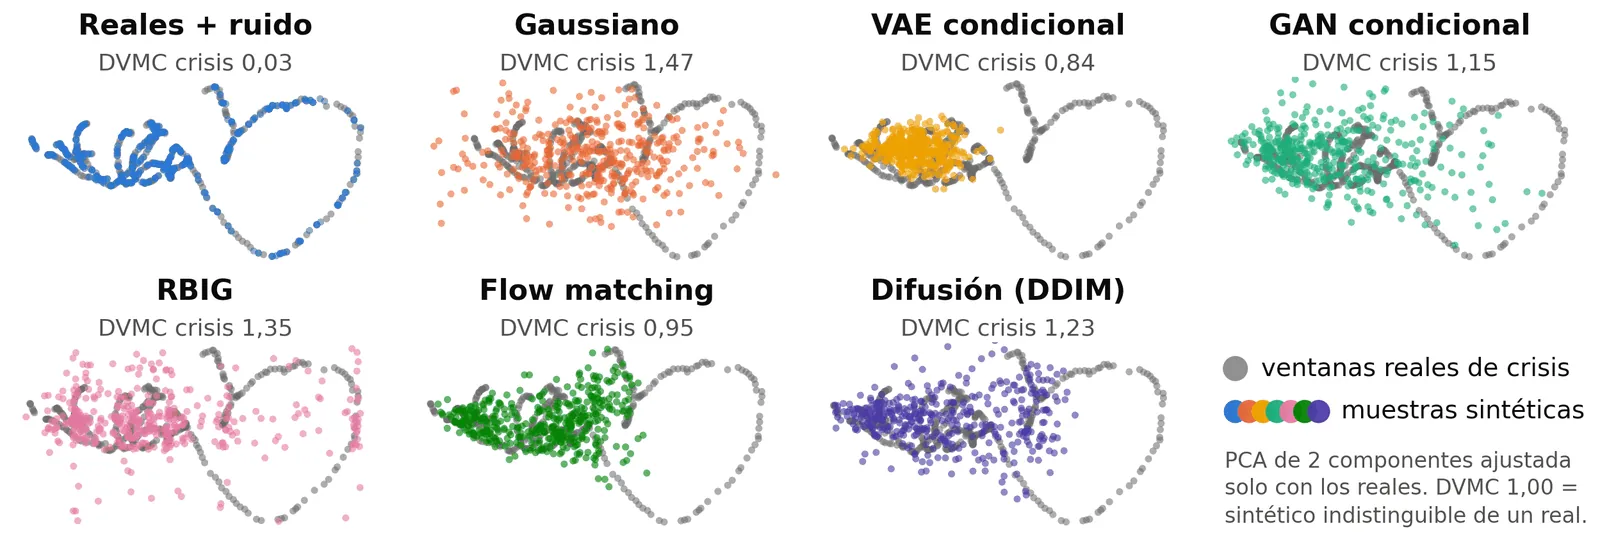
Can generative models help a classifier when real data is scarce? Here the scarcity is structural: from 2003 to 2026 there are about ten independent stress episodes. The task predicts the dominant market regime over the next 21 days from 60-day windows. We built seven generators, from real data plus noise to Gaussian, CVAE, CGAN, RBIG, flow matching and diffusion, with a time split, an 85-session embargo and test data that is always real.
Results
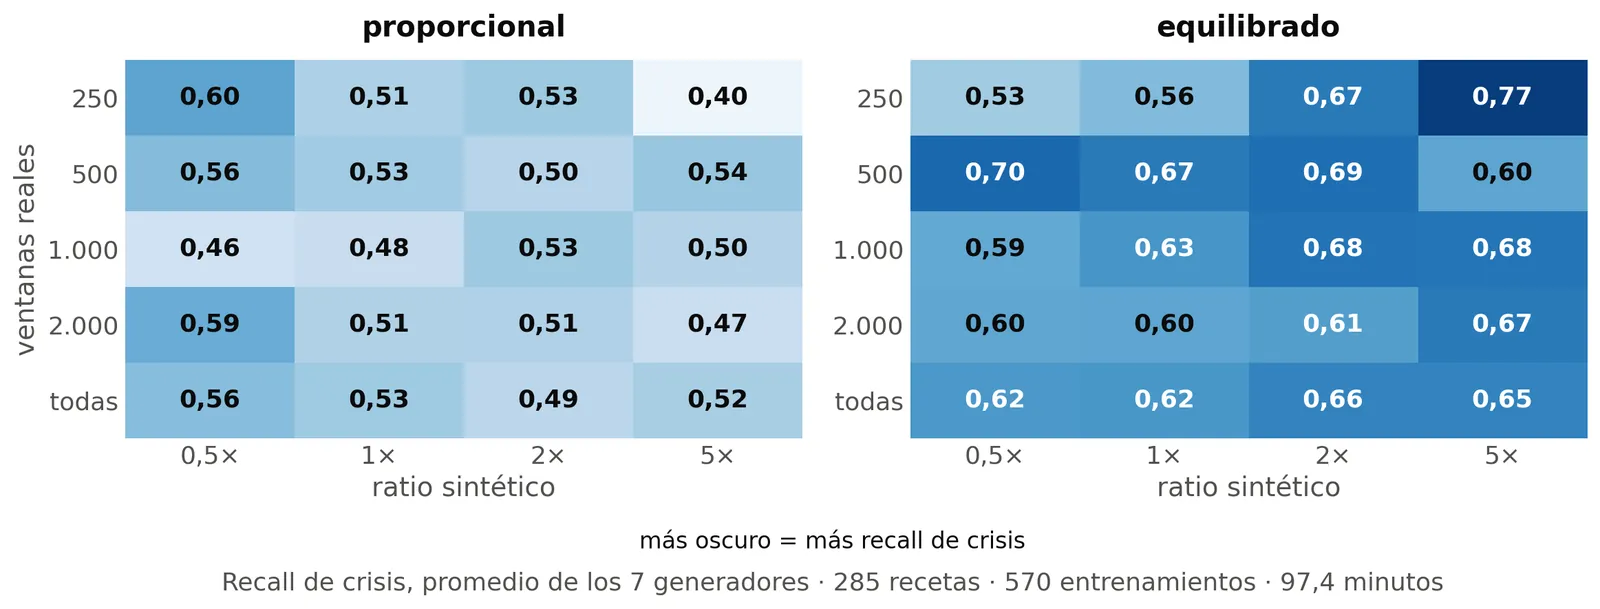
Across 570 training runs, synthetic data lifts balanced accuracy from 0.575 to 0.612 and beats reweighting the loss, but the gain sits inside the noise band. And the most faithful generator came seventh in usefulness.
Figures